
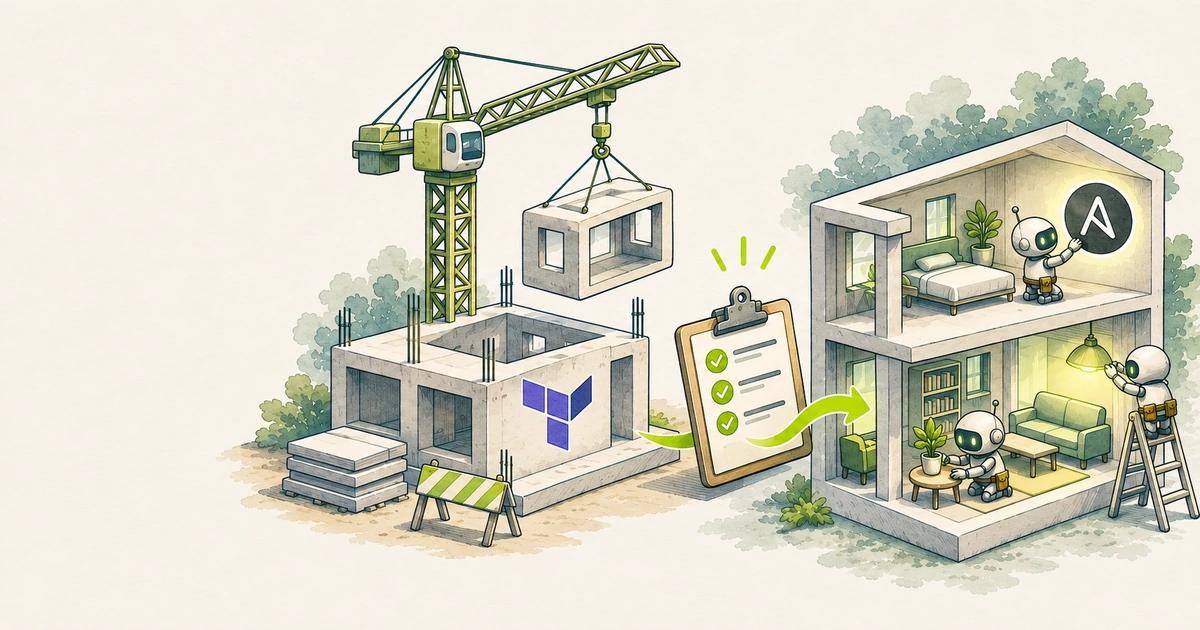
Terraform and Ansible are often compared as if you had to pick one. In practice many teams use both, because they are good at different things. The hard part is drawing a clean line between them and passing information from one to the other without copy-paste.
This guide explains that split and shows a working handoff: Terraform creates an EC2 instance, then Ansible configures it from an inventory built from Terraform outputs. If you are new to Terraform, the Terraform from Zero series on this blog covers the basics.
Different tools for different layers
- Terraform is declarative provisioning. It creates, changes and deletes infrastructure through provider APIs: networks, instances, databases, DNS records. It keeps a state file so it knows what exists.
- Ansible is configuration management. It connects to existing machines over SSH and makes sure the right packages, files, users and services are in place. It keeps no state; it checks the machine every run.
A useful rule: Terraform owns everything you could see in the cloud console; Ansible owns everything you would see after logging into the server.
Where teams go wrong
- Long `user_data` scripts in Terraform. They run once at boot, are hard to test, and changing them often replaces the instance.
- Terraform provisioners for configuration. HashiCorp's documentation describes provisioners as a last resort, because Terraform cannot model what they do.
- Ansible creating cloud resources. Ansible has cloud modules, but without a state file it is easy to drift or leak resources.
Keep each tool in its lane and the system stays predictable.
Step 1: Terraform creates the server and exposes outputs
A minimal example with the AWS provider:
resource "aws_instance" "web" {
  count         = 2
  ami           = var.ubuntu_ami_id
  instance_type = "t3.micro"
  key_name      = var.key_name
  vpc_security_group_ids = [aws_security_group.web.id]

  tags = {
    Name = "web-${count.index + 1}"
    Role = "web"
  }
}

output "web_public_ips" {
  value = aws_instance.web[*].public_ip
}
The output is the contract between the two tools. Ansible should depend on outputs, not on the internals of your Terraform code.
Step 2: Generate an Ansible inventory
The simplest handoff is to render outputs into an inventory file after terraform apply:
terraform output -json web_public_ips \
  | jq -r '"[web]", (.[] | "\(.) ansible_user=ubuntu")' > inventory.ini
That produces:
[web]
203.0.113.10 ansible_user=ubuntu
203.0.113.11 ansible_user=ubuntu
This is easy to understand and works anywhere jq is installed. The downside is that the file can go stale if someone changes infrastructure without regenerating it.
Step 2 (alternative): a dynamic inventory
For cloud environments, a dynamic inventory asks the provider for current machines every time Ansible runs. With the amazon.aws collection, create inventory.aws_ec2.yml:
plugin: amazon.aws.aws_ec2
regions:
  - eu-west-2
filters:
  tag:Role: web
  instance-state-name: running
keyed_groups:
  - key: tags.Role
    prefix: role
compose:
  ansible_host: public_ip_address
Install the collection and its Python dependencies, then check the result:
ansible-galaxy collection install amazon.aws
ansible-inventory -i inventory.aws_ec2.yml --graph
The tags you set in Terraform (Role = "web") now drive Ansible's groups. Nothing is copied by hand, and the inventory is always current.
Step 3: Wait for the server, then configure it
A fresh instance can take a minute before SSH works. Start the play with wait_for_connection so Ansible does not fail on a booting machine:
- name: Configure web servers
  hosts: role_web
  become: true
  gather_facts: false

  tasks:
    - name: Wait for SSH to come up
      ansible.builtin.wait_for_connection:
        timeout: 300

    - name: Gather facts now that the host is reachable
      ansible.builtin.setup:

    - name: Install Nginx
      ansible.builtin.apt:
        name: nginx
        state: present
        update_cache: true
gather_facts: false is important here; otherwise fact gathering would try to connect before the wait task runs.
Step 4: Run both in one pipeline
In CI, the steps are sequential and each one fails the job if it fails:
terraform -chdir=infra init -input=false
terraform -chdir=infra apply -input=false -auto-approve
ansible-playbook -i inventory.aws_ec2.yml site.yml
In a team pipeline, keep the plan-and-approve flow for Terraform (plan on pull request, apply after merge) and run Ansible only after a successful apply. Ansible runs are safe to repeat, so you can also schedule them nightly to correct configuration drift.
Handling replacements and immutable images
If you replace servers often, consider moving slow configuration into a machine image built with Packer, and use Ansible inside the Packer build. Terraform then launches instances from that image, and runtime Ansible only handles the few settings that change per environment. This keeps boot times short and servers identical.
Key takeaways
- Terraform provisions cloud resources and tracks them in state; Ansible configures what runs on the machines.
- Avoid provisioners and long
user_datascripts for configuration. - Treat Terraform outputs and tags as the contract Ansible depends on.
- Use a dynamic inventory in the cloud so Ansible always sees current servers.
- Start plays with
wait_for_connectionand keep the pipeline sequential: plan, apply, configure.
Sources: Terraform provisioners documentation, amazon.aws EC2 inventory plugin, ansible.builtin.wait_for_connection.
 Ansible for Beginners: Automate an Ubuntu Server with Your First Playbook4 min read
 Vercel Fluid Compute Explained: Concurrency, Active CPU Pricing and waitUntil4 min read
 Ingress-NGINX Is Retired: Migrate to Kubernetes Gateway API with ingress2gateway5 min read